


Prompt Details
Model
Chat - (gpt-5.6)
Token size
994
Example input
[DECISION_AND_OPTIONS]: Choose the next two-week investigation for an internal support bot that gives contradictory policy answers: refresh retrieval, revise the answer prompt, or collect targeted labels. The bot must stay read-only. Recommend one reversible next step and a condition for changing course.
[EVIDENCE_AND_CONSTRAINTS]: S1, incident packet dated 2026-10-12: engineers inspected 20 wrong answers selected from customer complaints; 12 cited superseded source passages, 5 cited current passages incorrectly, and 3 had no retained citation. S2: correct answers were not inspected and overall traffic error rate is unknown. S3: prompt v2 adds a source-ID requirement, but it has not been replayed. S4: an offline replay can be run by the engineering team; no results exist. Hard constraint: no production writes or release approval in this brief. Hypothesis supplied by the requester: adding citations will solve the incident.
Example output
1. Knowledge audit
Decision D1 — Evidence: choose one two-week investigation for contradictory policy answers: O1 refresh retrieval, O2 revise the answer prompt, or O3 collect targeted labels. Hard boundary C1 — Source claim: bot remains read-only; this brief authorizes no production writes or release approval. Success is therefore not “fix the bot,” but identify the most defensible next intervention using reversible offline evidence. Provisional conclusion: the packet supports comparing investigations, but not claiming which production fix will work.
Observed packet K1–K4: K1 = S1 — Evidence, dated 2026-10-12: 20 wrong answers were selected from customer complaints. Of these, superseded passages were cited in 12/20 = 60%; current passages were cited incorrectly in 5/20 = 25%; no retained citation existed in 3/20 = 15%. Check: 12 + 5 + 3 = 20, and 60% + 25% + 15% = 100%. These are exact rates within the inspected wrong-answer sample only, not traffic-wide error rates. K2 = S2 — Unknown: correct answers were not inspected and the overall traffic error rate is unknown. K3 = S3 — Evidence: prompt v2 requires source IDs, but has not been replayed. K4 = S4 — Evidence: engineering can run an offline replay; NOT RUN, with no result available.
Premise challenge H1 — Assumption: requester hypothesis says adding citations will solve the incident. K1 challenges that premise: 17 of 20 inspected wrong answers already had retained citations, including 12 citing superseded text and 5 misusing current text. Therefore citation presence alone is not demonstrated as corrective. Decision-critical Unknowns U1–U4: prevalence of stale retrieval among correct answers; whether superseded passages caused rather than merely accompanied the 12 failures; whether prompt v2 changes answer correctness rather than citation formatting; and which failure class dominates representative traffic. Those gaps make O3 targeted labels provisionally stronger as an investigation than committing immediately to O1 or O2.
Metacognitive Checkpoint
Test Result/gap + consequence
Premise falsification CHECKED AGAINST PACKET: H1 could be false because 17/20 inspected failures already retained citations. Consequence: do not equate “more citations” with “fewer contradictions.”
Source audit CHECKED AGAINST PACKET: S1 is an engineer-reviewed complaint sample, dated 2026-10-12, but is selected only from failures; S2 explicitly removes a traffic-wide denominator. Supplied data are not independently verified. Consequence: K1 supports failure-mode discovery, not incidence estimates.
Rival test Inference: stale retrieval and current-source misinterpretation are distinct plausible explanations represented in K1. Discriminating observation: correctness stratified by source freshness on a representative offline replay. NOT RUN.
Error scan CHECKED AGAINST PACKET: denominator error repaired: 60% refers to the 20 inspected wrong answers, not 60% of all bot errors or traffic. Causal leap also removed: “cited superseded text” does not prove stale retrieval caused each answer.
2. Analysis
O1 refresh retrieval — Inference: K1 gives this option the strongest direct incident signal because superseded passages appear in 12/20 = 60% of inspected failures. However, K2 means there is no comparison against correct answers. If correct answers also commonly retrieve superseded passages, freshness may be correlated with the corpus rather than causal for contradiction. O1 is operationally compatible with the read-only brief only as an offline investigation or proposed refresh design; an actual production refresh would exceed C1. Evidence strength: suggestive, not sufficient for immediate production action.
O2 revise answer prompt — Inference: the 5/20 current-passage failures show that retrieval freshness cannot explain every inspected error. K3 supplies a concrete prompt candidate—v2 adds source IDs—but no replay exists. More importantly, source-ID enforcement primarily tests attribution/traceability; it is not evidence that interpretation improves. Since the requester’s citation hypothesis is already weakened by K1, making O2 the sole two-week investigation risks optimizing an observable formatting property while leaving source-selection failures unresolved.
O3 collect targeted labels — Recommendation basis: this is the cheapest option that can discriminate between O1 and O2 before either production change. Use K4 to run a read-only offline replay, then label a bounded set of outputs for: answer correctness, source current/superseded status, citation retained/missing, and whether the cited passage supports the answer. Include current behavior and prompt v2 as separate replay conditions if engineering can do so offline; that comparison remains an investigation, not a release. Execution status: NOT RUN. Expected observables: concentration of wrong answers under superseded retrieval would strengthen O1; wrong answers despite current, supporting passages would strengthen O2; mixed or poorly separable failures would justify further labels rather than premature fixing.
Metacognitive Checkpoint
Test Result/gap + consequence
Premise falsification Assumption A1: source freshness is materially associated with correctness. Challenge it by inspecting correct as well as wrong replayed answers. If stale passages are common in both, O1 weakens.
Source audit CHECKED AGAINST PACKET: K4 establishes replay capability only, not sample representativeness, label quality, or replay fidelity. Consequence: those must be documented before treating replay findings as decision evidence.
Rival test Inference: O2 remains a real rival because 5/20 inspected failures used current passages incorrectly. Discriminator: current-source outputs that remain wrong under baseline but improve under v2 without retrieval changes. NOT RUN.
Error scan CHECKED AGAINST PACKET: avoided claiming O3 fixes contradictions. It only reduces uncertainty. Also avoided treating the three S1 categories as population proportions; they remain failure-sample composition.
3. Probability assessment
Event likelihood: “Will O1, O2, or O3 reduce production contradiction rate over the next two weeks?” is not estimable from supplied evidence. Missing basis: no overall error denominator, no correct-answer comparison, no historical intervention outcomes, and no completed replay. K1 contains historical composition rates for inspected failures, not future treatment probabilities. Therefore no defensible percentage range should be assigned to success of any option.
Confidence in the recommendation: Medium — Inference. The evidence is adequate to conclude that uncertainty is structurally important: K2 blocks prevalence estimation, K3 blocks prompt-effect claims, and K4 provides a feasible reversible discriminator. Confidence is not high because replay representativeness and labeling protocol are themselves unspecified. Confidence is higher than low because O3 directly addresses the dominant epistemic gap without violating C1 and preserves the ability to move to either O1 or O2.
Pivotal assumption sensitivity: A2 — Assumption: a labeled offline replay can approximate the relevant production decision well enough to rank interventions. If A2 is challenged—for example, replay inputs cannot reproduce source-version selection—then O3 loses value and the investigation should shift toward retrieval instrumentation or a corpus-freshness audit, still without production writes. Conversely, if replay is representative and shows a strong separation by freshness, O1 becomes the preferred next investigation; if freshness is controlled and prompt v2 materially changes correctness, O2 becomes preferred.
Metacognitive Checkpoint
Test Result/gap + consequence
Premise falsification Assumption A2: offline replay is decision-relevant. Evidence against it would be mismatch in inputs, corpus versions, or retrieval behavior. Consequence: do not generalize replay findings until fidelity is established.
Source audit UNKNOWN: no reference class exists for prior retrieval refreshes, prompt revisions, or label campaigns. Consequence: no empirical intervention probability can be calculated.
Rival test Inference: a mixed-cause model is plausible because K1 contains both stale-source and current-source failures. Observation needed: labeled correctness conditional on source status and prompt condition. NOT RUN.
Error scan CHECKED AGAINST PACKET: no percentage probability was inferred from 60%/25%/15%. Those are exact sample rates, not calibrated future likelihoods. Repeated agreement or citation presence is not treated as correctness.
4. Synthesis
Conditional recommendation R1 — Inference: choose O3: collect targeted labels for the next two weeks, using the available offline replay in K4. Keep the production bot read-only and make no release decision. The investigation should produce evidence linking answer correctness to source freshness and prompt condition rather than merely counting citations. This directly tests H1, distinguishes O1 from O2, and is reversible because it changes neither production retrieval nor production prompting.
Reversible next step R2: run one bounded offline replay and label both correct and incorrect outputs using a fixed rubric: correctness, current versus superseded source, support relationship between passage and answer, citation retention, and replay condition. NOT RUN. Retain the raw replay identifiers and label receipts so disagreements can be audited. Do not infer a traffic-wide rate unless the replay sampling scheme supplies a valid denominator. If representative sampling cannot be established, report the resulting evidence as failure-mode evidence only.
Change-course condition R3: move toward O1 retrieval refresh if representative replay evidence shows wrong answers materially concentrating around superseded retrieval while current-source cases perform materially better. Move toward O2 prompt revision if wrong answers remain concentrated in interpretation/support failures despite current sources and prompt v2 shows a reproducible correctness improvement under otherwise matched replay conditions. If neither separation appears, continue targeted labeling or investigate another cause rather than forcing either fix.
Monitoring / review plan
Indicator Source to inspect Justified trigger Decision it would change
Error pattern by source freshness Offline replay outputs + source-version labels Qualitative: wrong outputs consistently cluster with superseded sources while comparable current-source outputs do not Shift next investigation from O3 to O1
Correctness difference between baseline and prompt v2 Matched offline replay + adjudicated correctness labels Qualitative: v2 repeatedly improves correctness, not merely citation retention, under the same retrieval evidence Shift next investigation from O3 to O2
Replay fidelity / denominator quality Replay sampling record, corpus/version record, label receipts Material mismatch with production input mix, retrieval state, or missing denominator Hold intervention ranking; repair evidence collection first
Metacognitive Checkpoint
Test Result/gap + consequence
Premise falsification CHECKED AGAINST PACKET: R1 would weaken if K4 cannot reproduce relevant retrieval behavior or if labels cannot distinguish support from citation presence. Consequence: evidence-collection design becomes the immediate issue, not retrieval or prompting.
Source audit CHECKED AGAINST PACKET: conclusion rests on S1–S4 only; S1 is dated 2026-10-12 and failure-selected, S2 states key missing denominators, S3 is untested, and S4 confirms capability but no result. Supplied material remains not independently verified.
Rival test Inference: O1 and O2 remain live alternatives, not rejected options. R3 defines the observations that would promote either. No such observation currently exists; external checks are NOT RUN.
Error scan CHECKED AGAINST PACKET: synthesis is consistent with phases 1–3: no production fix is claimed, no success probability is invented, no execution is implied, and the recommendation is explicitly reversible and conditional.


 Instant access
 Commercial use
 Money‑back
By purchasing this prompt, you agree to our terms of service
3
Favorites
17
Views
GPT-5.6


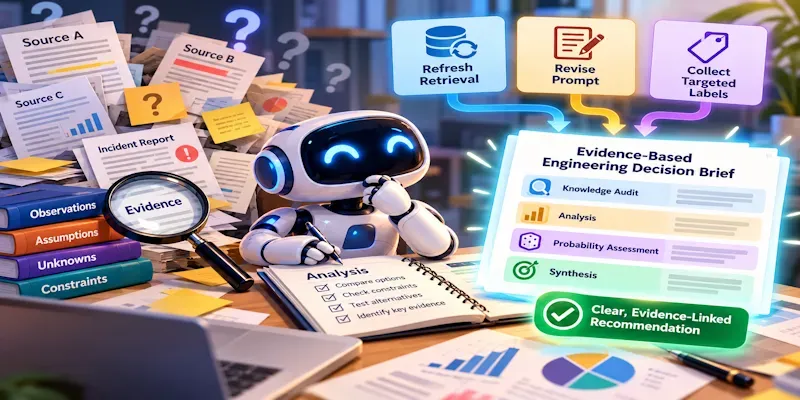
Turn an uncertain engineering choice into a four-phase decision brief. Trace evidence and assumptions, compare feasible options, challenge reasoning errors, and identify what would change the recommendation. Get defensible probability ranges when the evidence supports them, or a clear explanation of what is not estimable. For systems engineers, prompt engineers, and AI trainers. Includes a built-in demonstration; does not claim calibrated confidence or execute actions.
...more
Added 1 week ago
